Core Concepts
The fundamental building blocks of spatial feature extraction.
Convolution
Learn how sliding kernels extract features from spatial data through mathematical dot products.
Learn trending_flatReceptive Fields
Visualize the area in the input image that a single neuron in a specific layer is sensitive to.
Learn trending_flatVanishing Gradients
Explore why deep networks struggle to train and how ResNets solved the signal attenuation problem.
Learn trending_flatAttention
See how transformers let every position decide which other parts of the input to listen to, and by how much.
Learn trending_flatTrained Models
Live inference and internal activation visualization on real datasets.
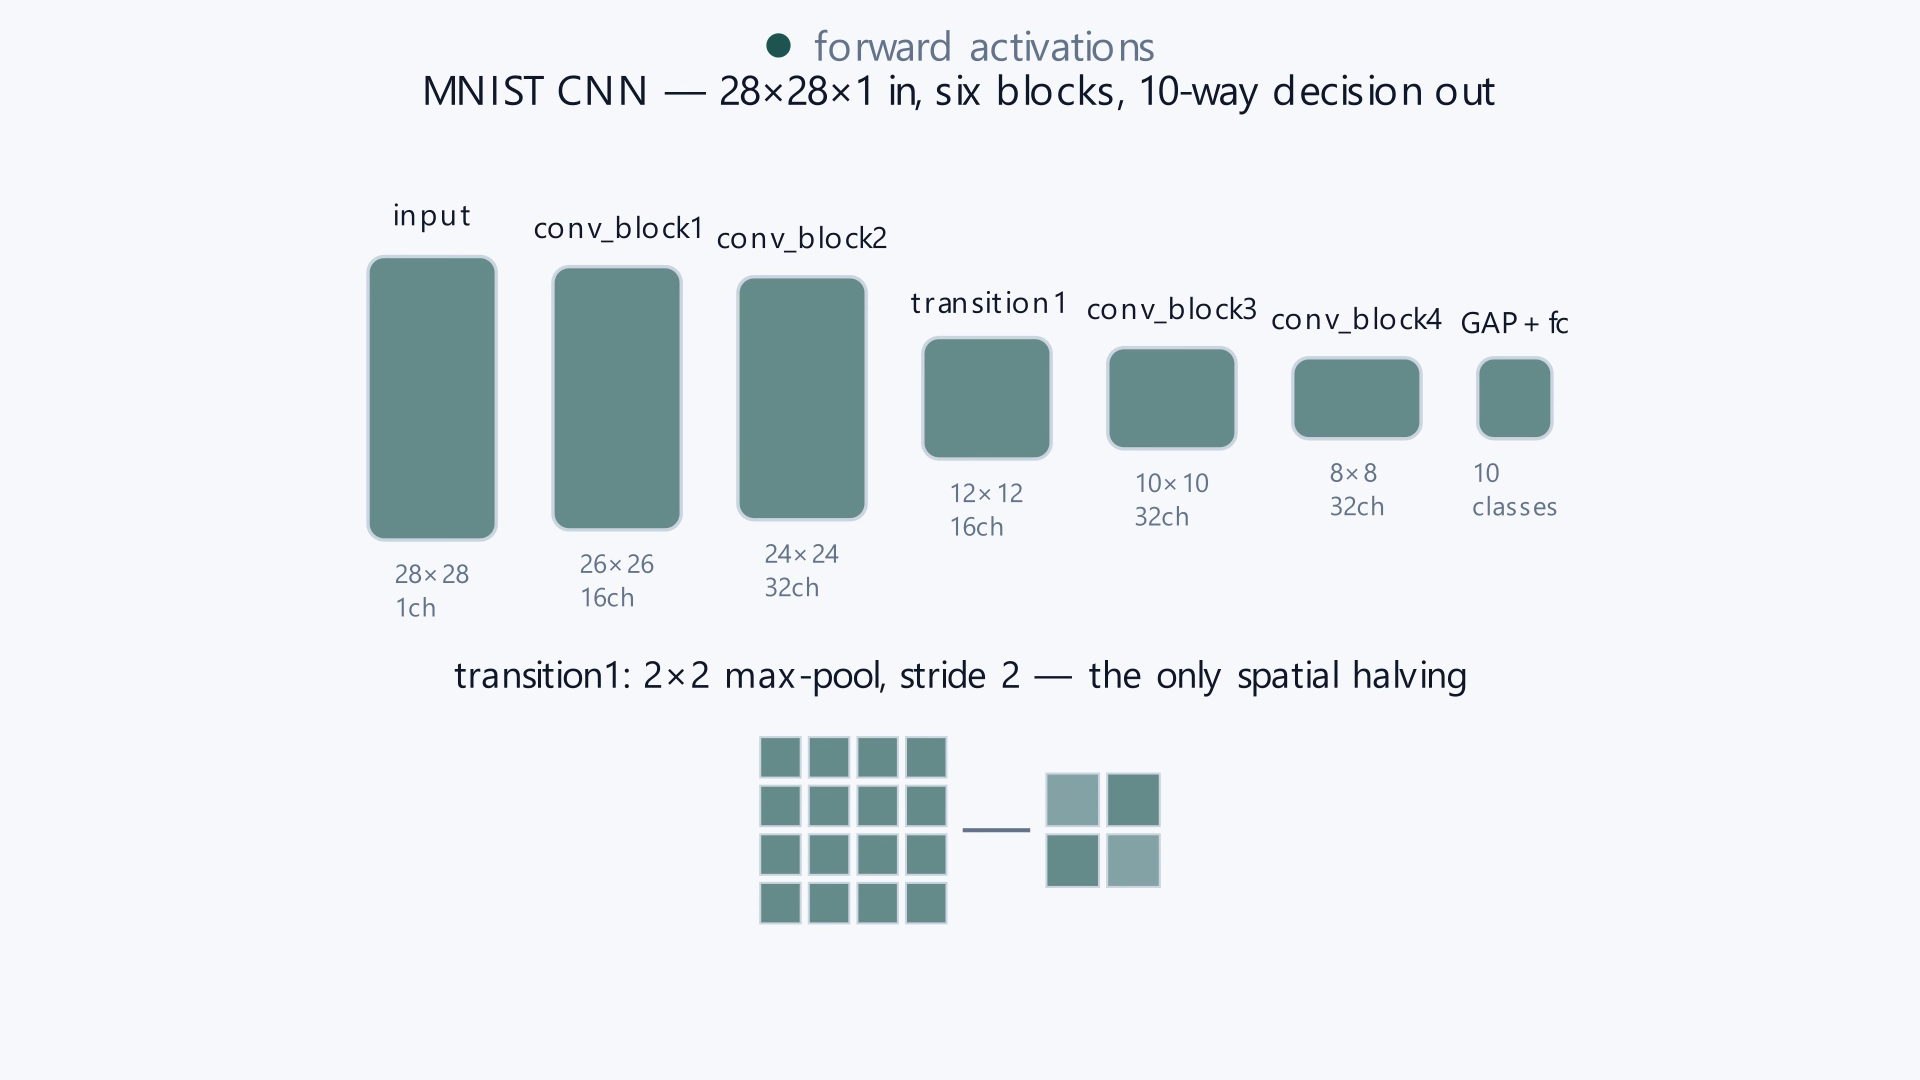 99.2% Acc
Simple CNN
A lightweight 3-layer architecture, perfect for learning the basics of digit recognition.
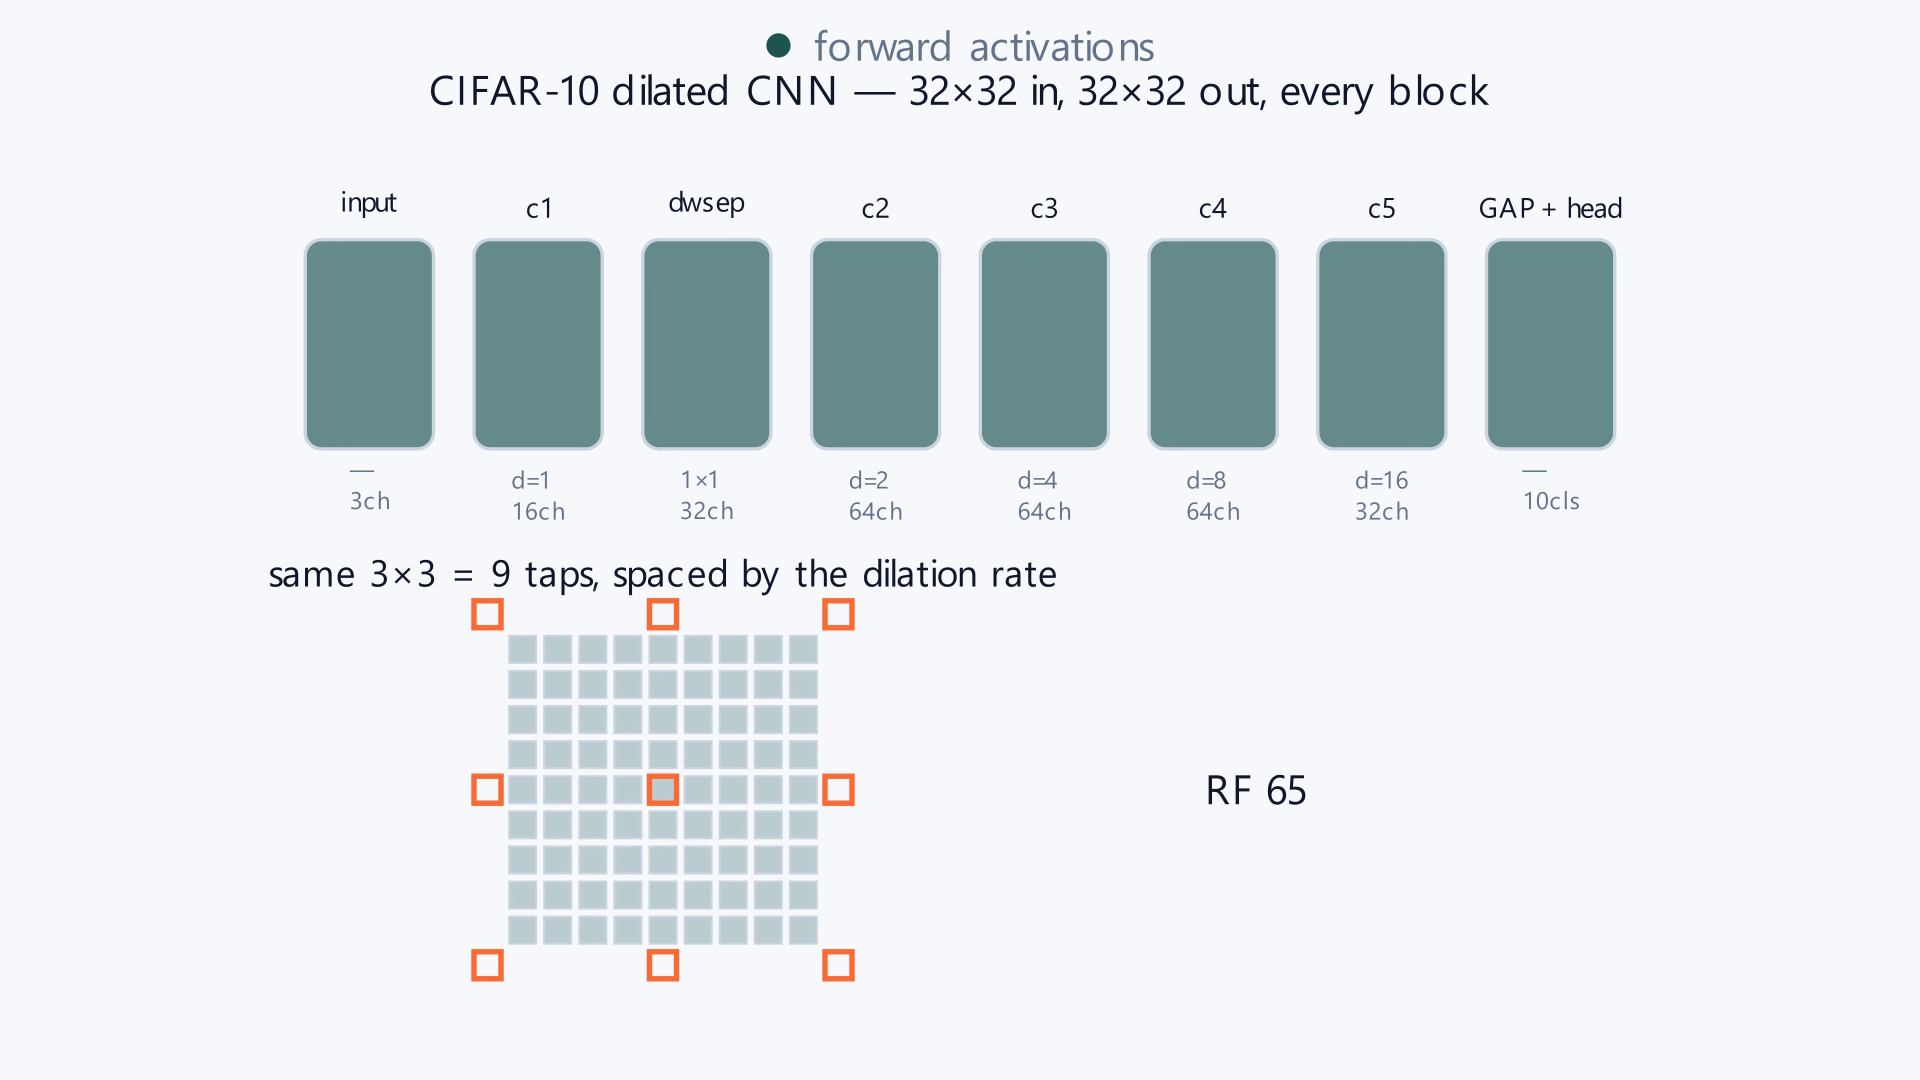 88.4% Acc
Dilated CNN
Explores dilated convolutions for increased receptive fields without pooling layers.
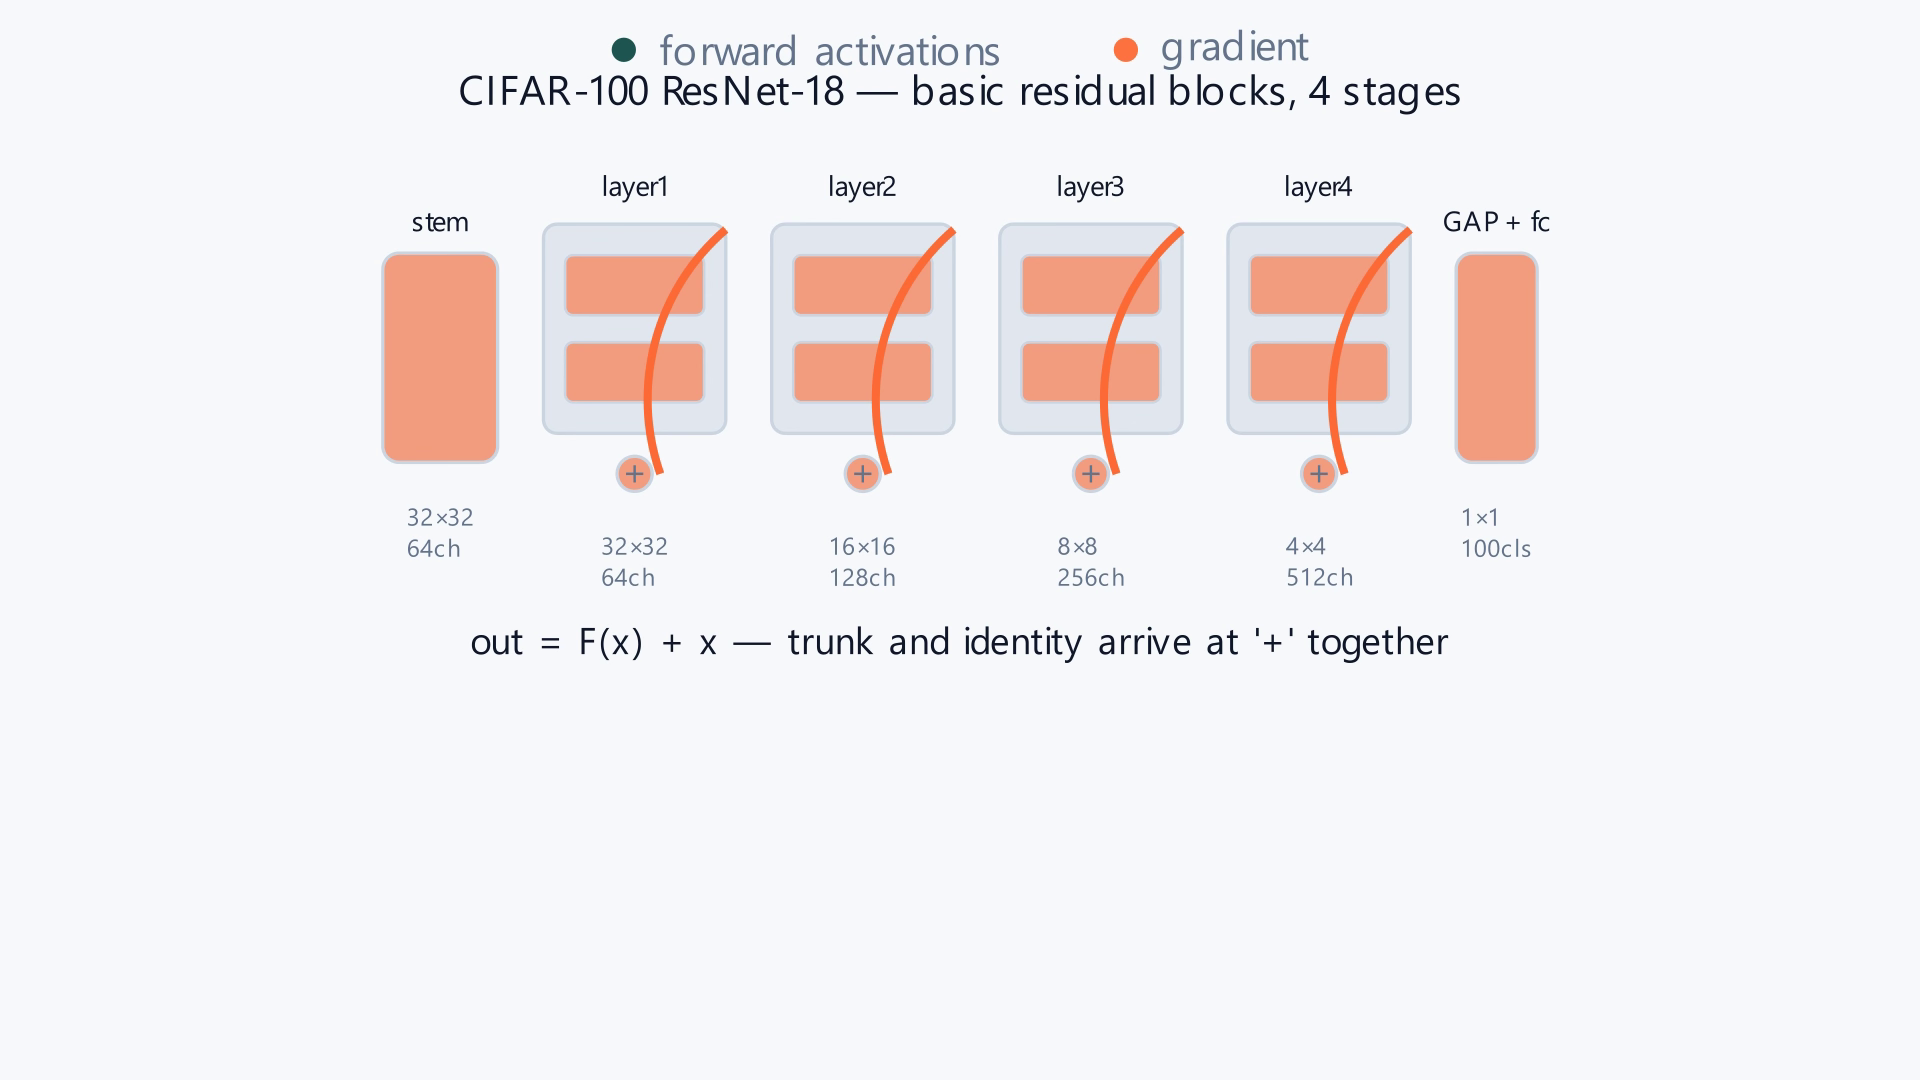 76.6% Acc
ResNet-18
A residual network demonstrating how skip connections enable deeper feature extraction.
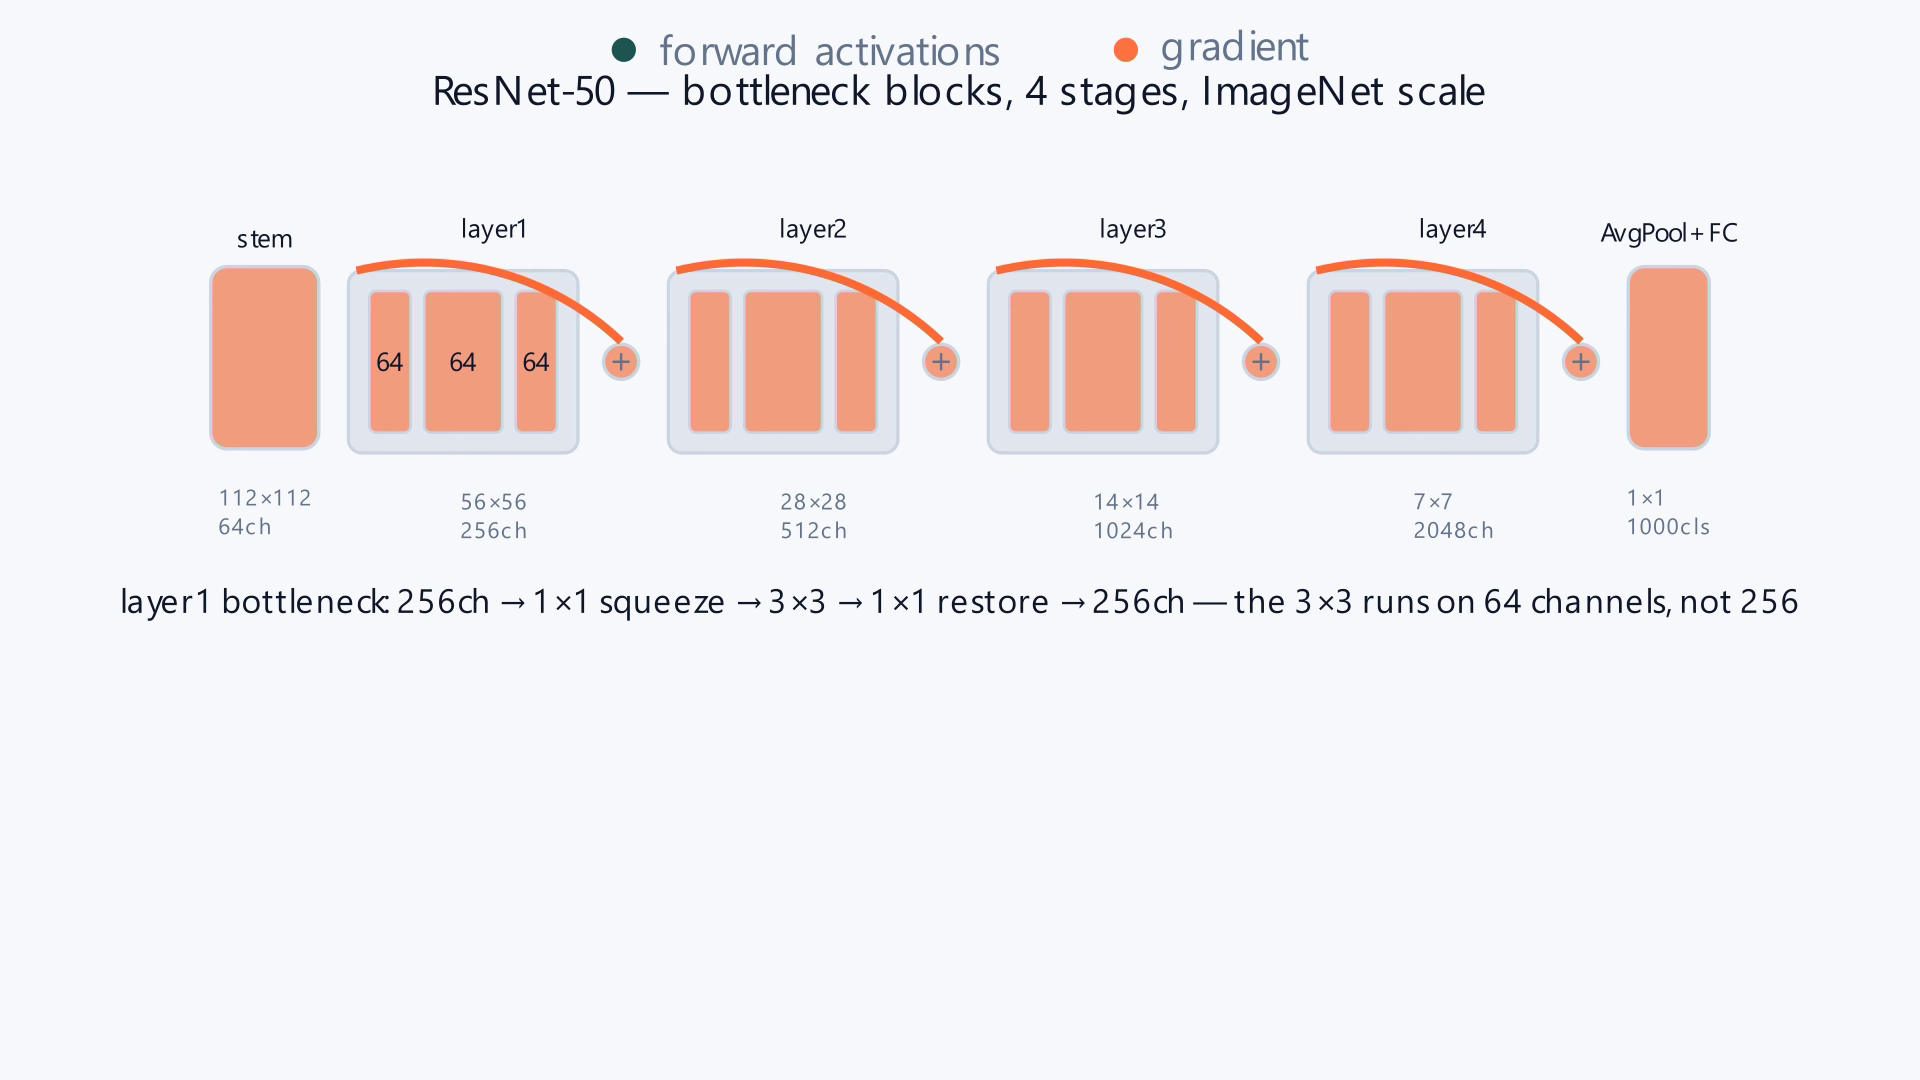 76.01% top-1
ResNet-50
The gold standard for object classification. Inspect activations on a per-channel basis.
 97.2% orig · 94.9% clean
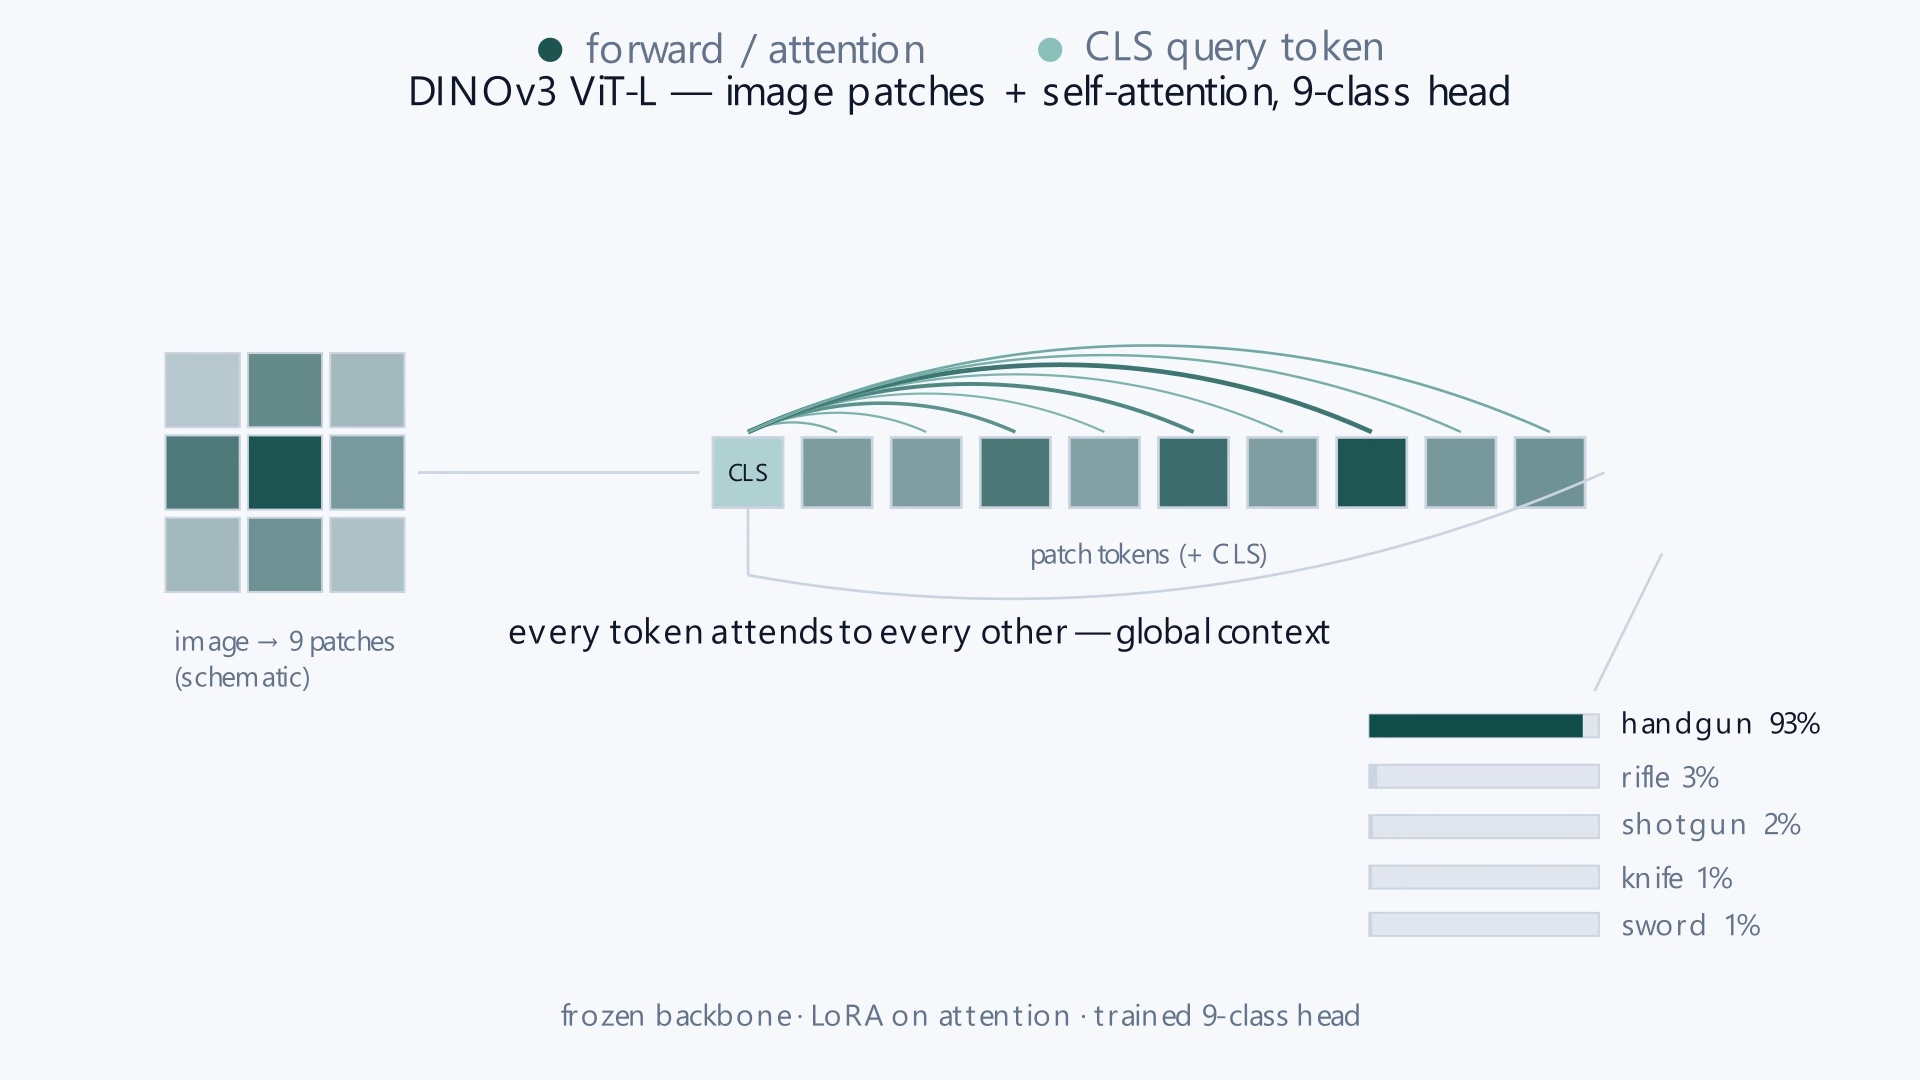
DINOv3 ViT-L
Meta's self-supervised vision transformer, LoRA-tuned to nine weapon classes — the attention half of an attention-vs-convolution study.
 96.5% orig · 96.9% clean
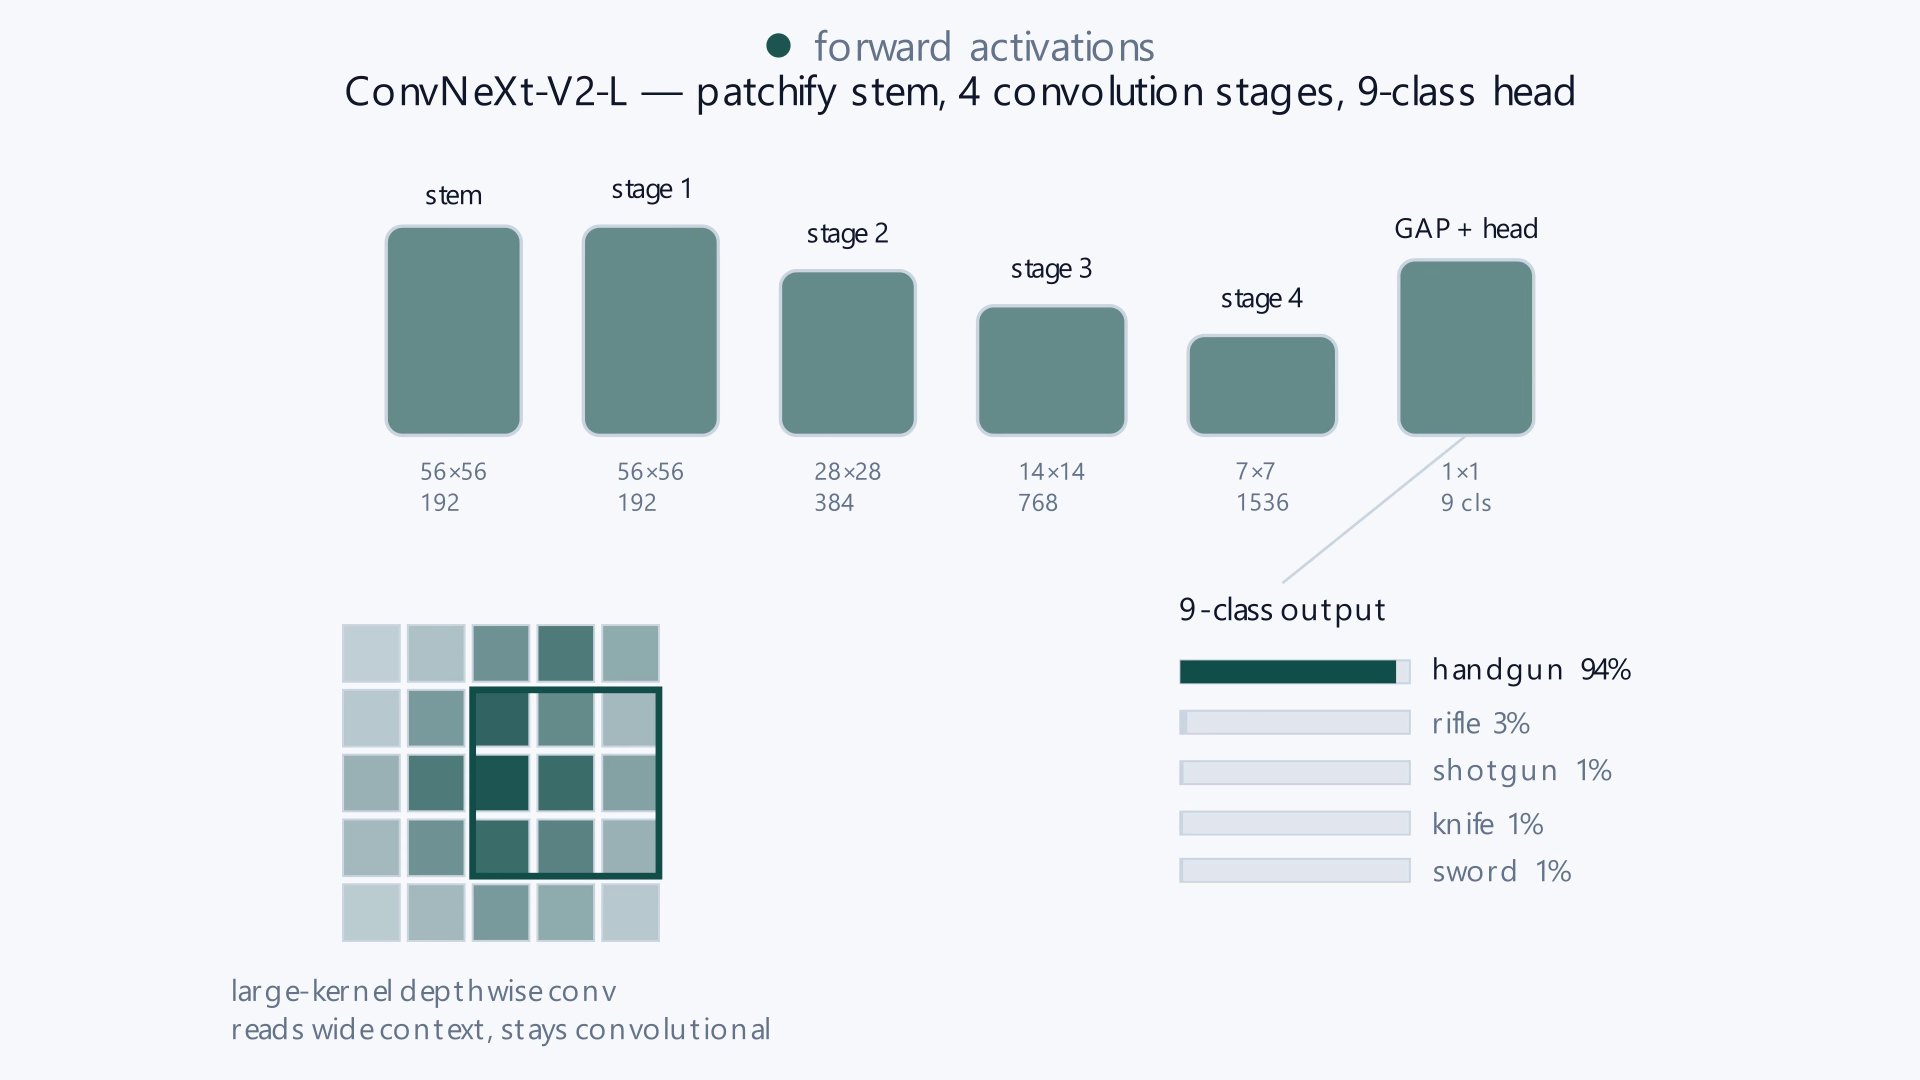
ConvNeXt-V2-L
A modern convolutional network fine-tuned on nine weapon classes — the convolution counterpart that ties DINOv3 on clean data.
ViT — Coming Soon
Vision Transformer integration in progress.